Skip to content
Apiyi.com Blog

Apiyi.com Blog

Best AI API Router Services

  • Nano Banana Pro🔥
  • Free AI Imagen
  • DocsExpand
    • ChangeLog
    • Models
    • Scenarios
  • APIYI DashboardExpand
    • Logs
    • KEY(Token)
    • Recharge
    • Back APIYI Home
    • Register APIYI
Apiyi.com Blog
Apiyi.com Blog
Best AI API Router Services
  • claude mythos preview anthropic cybersecurity model introduction en image 0 图示
    AI Coding | LLM API News

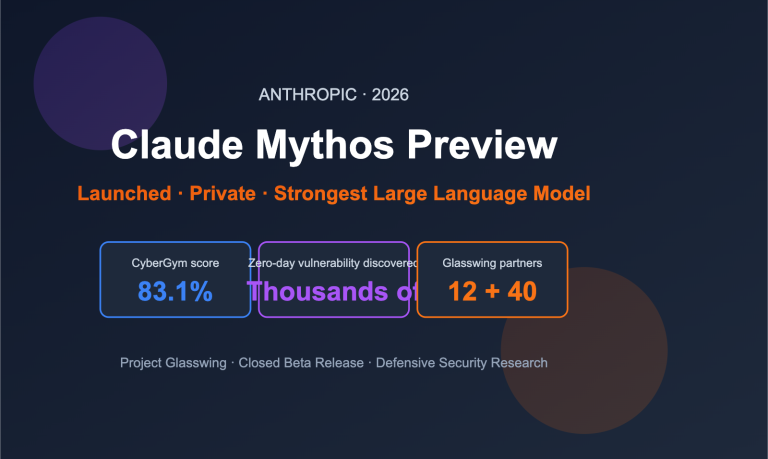
    In-depth interpretation of Claude Mythos Preview: 5 core capabilities of Anthropic’s most powerful Large Language Model

    ByAPIYI - Stable and affordable AI API 2026年 4月 8日

    title: "Anthropic's Secret Weapon: Decoding the Claude Mythos Preview" description: "Anthropic quietly launched its most powerful model yet, Claude Mythos Preview. Here's a quick breakdown of its capabilities and why it's being kept under wraps." tags: [AI, Anthropic, Claude, Cybersecurity, Tech News] On April 7, 2026, Anthropic quietly launched its most powerful model to date—Claude…
    Read More In-depth interpretation of Claude Mythos Preview: 5 core capabilities of Anthropic’s most powerful Large Language ModelContinue

  • happyhorse model mystery ai video lmarena analysis en image 0 图示
    LLM API News | Video AI API

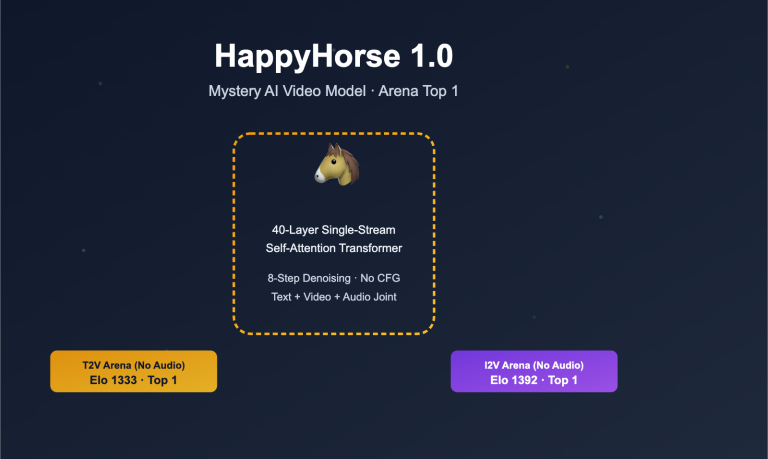
    HappyHorse model decryption: A complete analysis of the AI video dark horse that mysteriously topped the Arena and then disappeared

    ByAPIYI - Stable and affordable AI API 2026年 4月 8日

    In early April 2026, a mysterious AI video model named HappyHorse quietly appeared on the Artificial Analysis Video Arena blind test leaderboard. Both its V1 and V2 versions simultaneously climbed to the top of the Text-to-Video and Image-to-Video rankings, shattering Elo scores and leaving industry heavyweights like Seedance 2.0, Kling 3.0, and PixVerse V6 in…

    Read More HappyHorse model decryption: A complete analysis of the AI video dark horse that mysteriously topped the Arena and then disappearedContinue

  • microsoft mai 3 models transcribe voice image guide en image 0 图示
    LLM API News

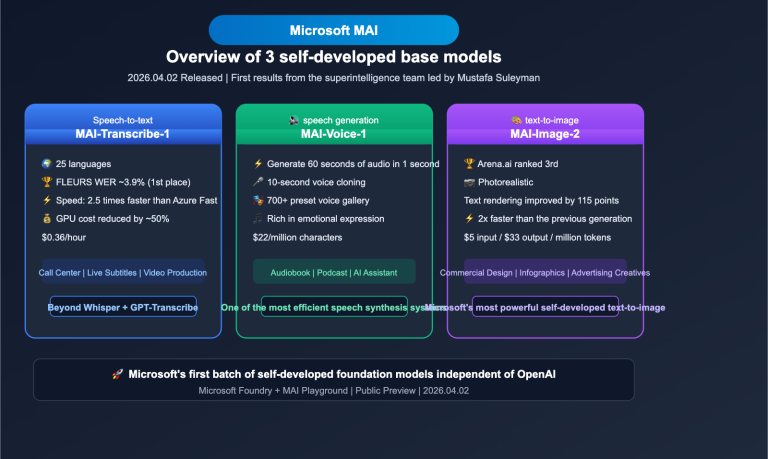
    Interpretation of Microsoft’s 3 New Models: MAI-Transcribe-1, MAI-Voice-1, and MAI-Image-2 Technical Specifications and API Integration Guide

    ByAPIYI - Stable and affordable AI API 2026年 4月 7日

    On April 2, 2026, the Microsoft MAI Super Intelligence team officially released 3 proprietary foundation models: MAI-Transcribe-1 (speech-to-text), MAI-Voice-1 (speech generation), and MAI-Image-2 (text-to-image). This marks the first major product launch since the formation of the MAI team under Mustafa Suleyman, signaling Microsoft's move to build AI capabilities independent of OpenAI. Core Value: Get up…

    Read More Interpretation of Microsoft’s 3 New Models: MAI-Transcribe-1, MAI-Voice-1, and MAI-Image-2 Technical Specifications and API Integration GuideContinue

  • qwen3 6 plus 429 error fix api guide en image 0 图示
    Qwen API | Solutions

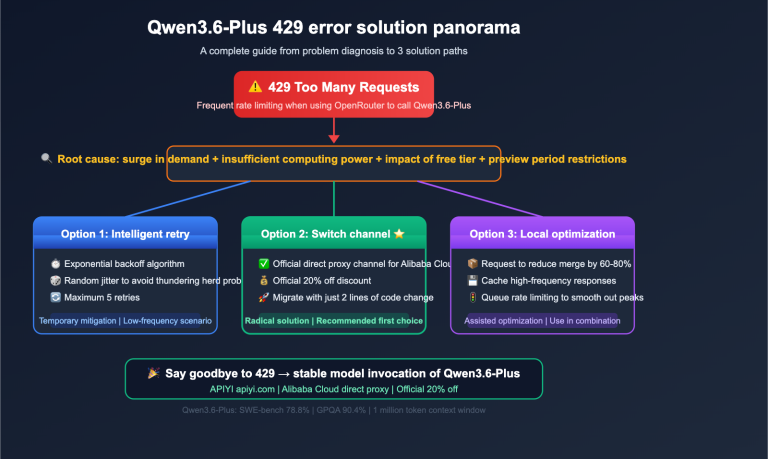
    3 Solutions to Resolve Qwen3.6-Plus 429 Errors: Say Goodbye to OpenRouter Rate Limiting, Stable Model Invocation Guide

    ByAPIYI - Stable and affordable AI API 2026年 4月 7日

    If you've worked with Qwen3.6-Plus, you’ve likely felt the pain: when calling this model via OpenRouter, the 429 Too Many Requests error has become a daily occurrence. Even if you've topped up your account and aren't on a free tier, you're still getting rate-limited to the point of frustration. Core Value: This article dives deep…

    Read More 3 Solutions to Resolve Qwen3.6-Plus 429 Errors: Say Goodbye to OpenRouter Rate Limiting, Stable Model Invocation GuideContinue

  • grok imagine quality speed mode guide en image 0 图示
    Grok API | Image Generation API

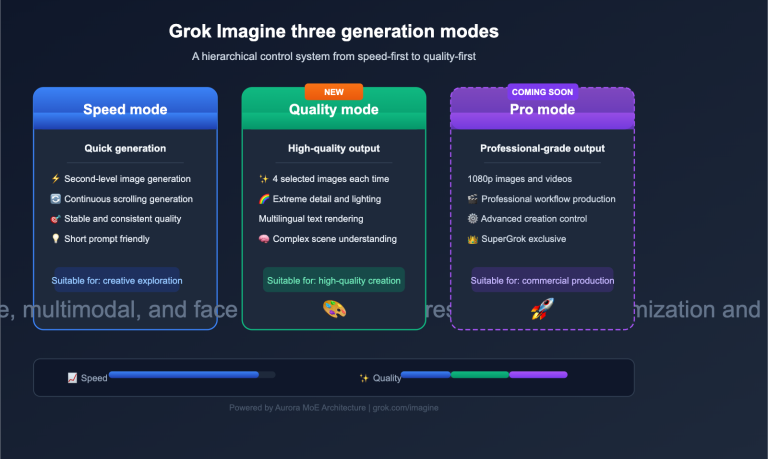
    Mastering the 3 Grok Imagine generation modes: A complete guide to Quality, Speed, and the upcoming Pro mode

    ByAPIYI - Stable and affordable AI API 2026年 4月 6日

    On April 3, 2026, xAI officially launched two brand-new generation modes for Grok Imagine: Quality and Speed. They also teased a Pro mode, set to arrive at the end of April. This update marks a shift for AI image generation tools, moving away from "one-click generation" toward a new era of "layered quality control." Core…

    Read More Mastering the 3 Grok Imagine generation modes: A complete guide to Quality, Speed, and the upcoming Pro modeContinue

  • gpt image 2 openai next gen image model leak preview guide en image 0 图示
    Image Generation API | OpenAI API

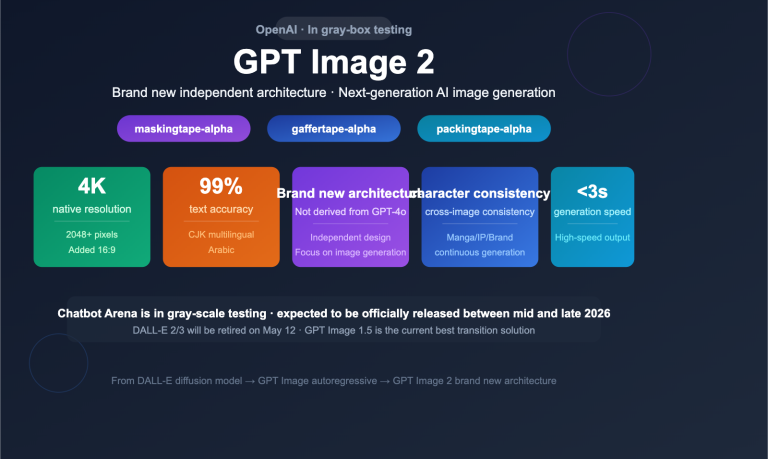
    Preview of GPT Image 2: 3 Grayscale Codenames Exposed and a Comprehensive Interpretation of 5 Major Expected Upgrades

    ByAPIYI - Stable and affordable AI API 2026年 4月 6日

    OpenAI's next-generation image generation model, GPT Image 2, has entered the gray-box testing phase, with three codenamed models (maskingtape/gaffertape/packingtape) appearing in anonymous evaluations on the Chatbot Arena. Although not yet officially released, leaked information suggests that GPT Image 2 utilizes a brand-new, independent architecture, with expected breakthroughs in text rendering, resolution, multilingual support, and face…

    Read More Preview of GPT Image 2: 3 Grayscale Codenames Exposed and a Comprehensive Interpretation of 5 Major Expected UpgradesContinue

  • gpt image 2 preview leak maskingtape arena guide en image 0 图示
    Image Generation API | LLM API News

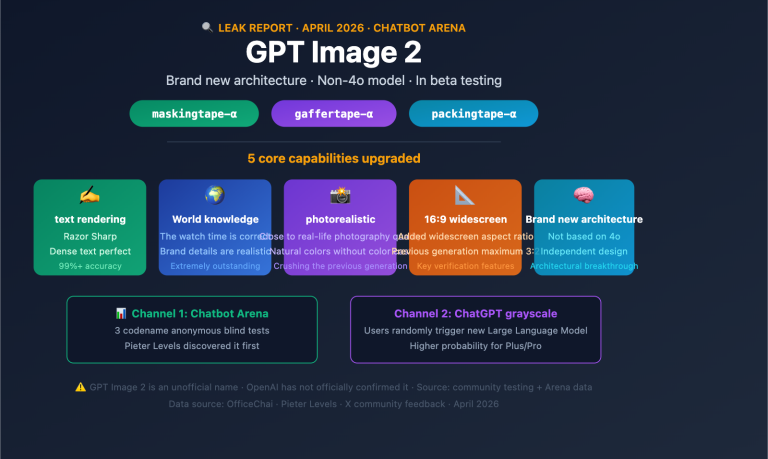
    Full Interpretation of GPT Image 2 Grayscale Leak: 3 Codename Models Appear in Arena, 5 Major Capability Upgrades, and Trigger Verification Techniques

    ByAPIYI - Stable and affordable AI API 2026年 4月 5日

    Author's Note: A detailed look at the latest developments in the OpenAI GPT Image 2 beta test, including the performance of the maskingtape/gaffertape/packingtape models in anonymous Arena testing, tips for triggering 16:9 widescreen output, and key differences from GPT Image 1.5. OpenAI hasn't officially released GPT Image 2 yet, but this new model has been…

    Read More Full Interpretation of GPT Image 2 Grayscale Leak: 3 Codename Models Appear in Arena, 5 Major Capability Upgrades, and Trigger Verification TechniquesContinue

  • openclaw claude llm request rejected extra usage fix en image 0 图示
    AI Coding | Solutions

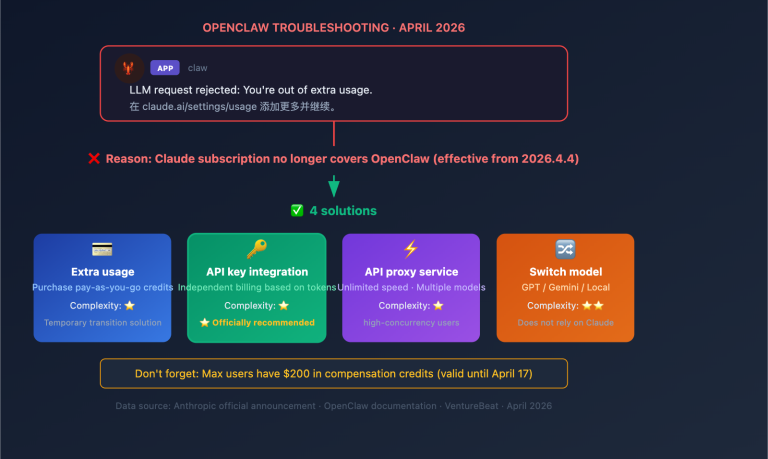
    4 solutions to resolve the OpenClaw error LLM request rejected You’re out of extra usage

    ByAPIYI - Stable and affordable AI API 2026年 4月 5日

    Author's Note: This guide provides a detailed breakdown of why you're seeing the "LLM request rejected: You're out of extra usage" error when using Claude in OpenClaw, along with 4 proven solutions—including topping up Extra Usage, switching API keys, and using an unlimited-speed API proxy service. Running into the LLM request rejected: You're out of…

    Read More 4 solutions to resolve the OpenClaw error LLM request rejected You’re out of extra usageContinue

  • gemini 3 1 pro 429 rate limit quota exceeded fix guide en image 0 图示
    Error Codes & Troubleshooting | Gemini API

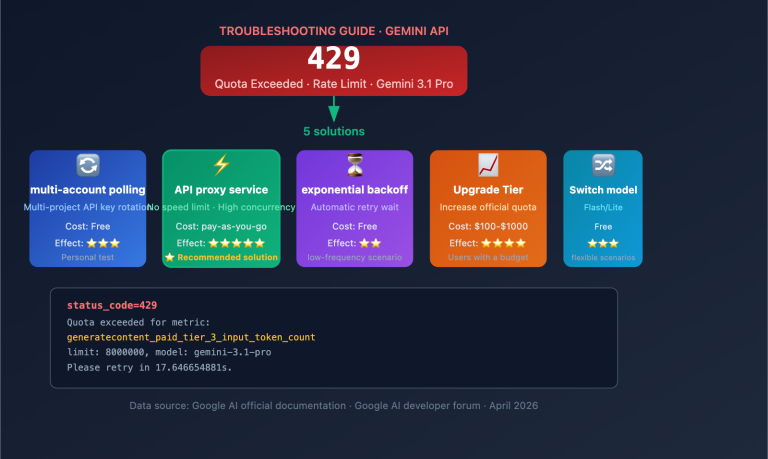
    5 Solutions to Resolve Gemini 3.1 Pro 429 Rate Limit Errors: From Multi-Account Polling to Unlimited API Proxy Service

    ByAPIYI - Stable and affordable AI API 2026年 4月 5日

    Author's Note: A detailed breakdown of the causes behind the Gemini 3.1 Pro API 429 Quota Exceeded error and 5 practical solutions, including key rotation across multiple AI Studio accounts, high-concurrency API proxy services, and exponential backoff retry strategies. Running into frequent 429 rate limit errors when using the Gemini 3.1 Pro API is one…

    Read More 5 Solutions to Resolve Gemini 3.1 Pro 429 Rate Limit Errors: From Multi-Account Polling to Unlimited API Proxy ServiceContinue

  • qwen3 5 omni multimodal model text audio video realtime en image 0 图示
    LLM API News | Qwen API

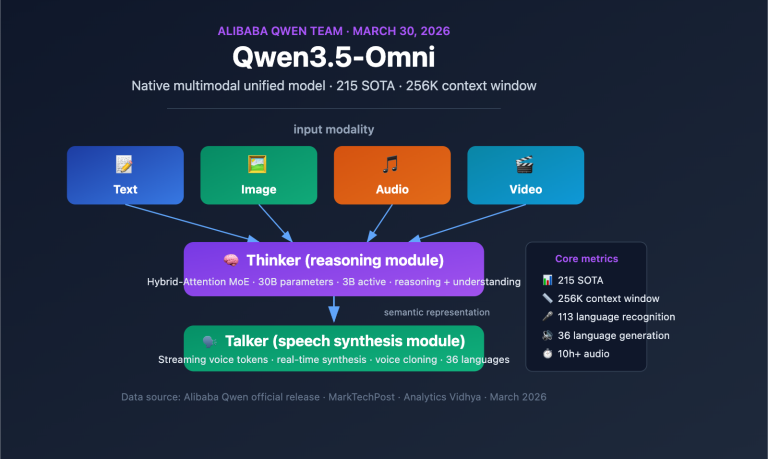
    Decoding Qwen3.5-Omni Native Multimodal Model: Thinker-Talker Architecture Achieves Unified Processing of 4 Modalities and Speech Recognition for 113 Languages

    ByAPIYI - Stable and affordable AI API 2026年 4月 4日

    description: A deep dive into the Qwen3.5-Omni native multimodal model, covering its Thinker-Talker MoE architecture, 256K context window, and Audio-Visual Vibe Coding capabilities. Author's Note: A detailed breakdown of the Alibaba Qwen3.5-Omni native multimodal model, covering its Thinker-Talker MoE architecture, 256K context window, audio-video encoding capabilities, and the emergent Audio-Visual Vibe Coding ability. On March…

    Read More Decoding Qwen3.5-Omni Native Multimodal Model: Thinker-Talker Architecture Achieves Unified Processing of 4 Modalities and Speech Recognition for 113 LanguagesContinue

Page navigation

Previous PagePrevious 1 … 18 19 20 21 22 … 60 Next PageNext

© 2026 Apiyi.com Blog - WordPress Theme by Kadence WP

Scroll to top
  • Nano Banana Pro🔥
  • Free AI Imagen
  • Docs
    • ChangeLog
    • Models
    • Scenarios
  • APIYI Dashboard
    • Logs
    • KEY(Token)
    • Recharge
    • Back APIYI Home
    • Register APIYI
  • 简体中文 (Chinese (Simplified))
  • 繁體中文 (Chinese (Traditional))
  • English
  • Русский (Russian)
  • 日本語 (Japanese)
  • 한국어 (Korean)
  • العربية (Arabic)
  • Français (French)
  • Deutsch (German)
  • Indonesia (Indonesian)
  • Português (Portuguese (Portugal))
  • Español (Spanish)